
A proposal is not a decision
A design review discusses three vendors. Someone says Vendor B looks promising, another raises a compliance concern, and the group agrees to investigate. An AI summary labels Vendor B the chosen supplier. The text is fluent, but the organization never made that decision. If an agent later treats the summary as policy, a tentative conversation has become an unauthorized instruction.
This is why extracting likely rationale and approving organizational memory are different jobs.
What AI extraction is good at
Models can scan meeting transcripts, email chains and tickets to propose the decision statement, alternatives, supporting evidence, participants and unresolved questions. They can also link a candidate back to time-stamped source passages. The result is useful because reviewers no longer start from a blank form.
But extraction remains an interpretation. A model may overlook dissent, confuse a recommendation with approval, or merge statements from different meetings into one apparently coherent conclusion.
Design the approval boundary
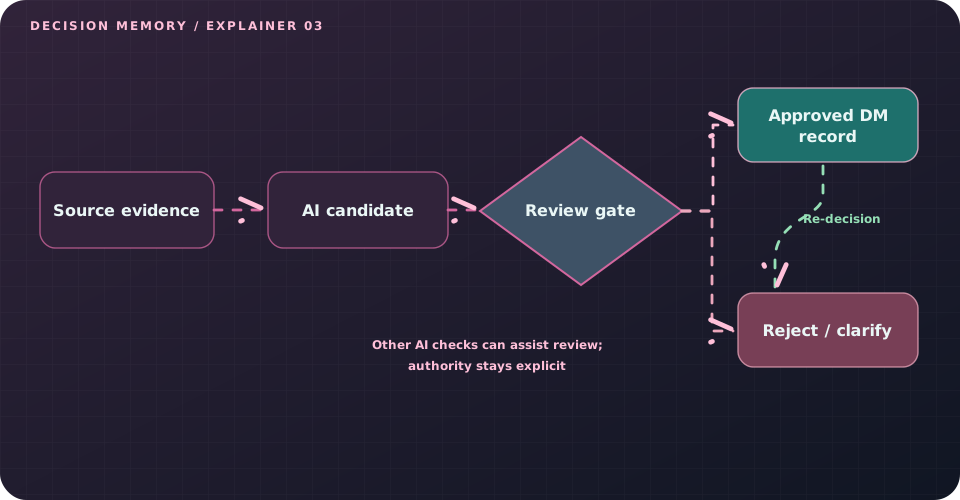
A practical workflow starts with source evidence. AI extracts a candidate and marks uncertainty. A reviewer sees the proposed choice, alternatives and exact supporting passages. The reviewer can approve, reject or request clarification. Only an approved item becomes a durable, searchable decision record with owner, scope, effective date and status.
If new evidence challenges it later, the workflow should create a re-decision candidate linked to the original record. The history remains available while the current approved state changes.
Reduce reviewer fatigue without faking authority
Human approval need not mean manually rereading every transcript. Another specialized AI tool or agent can check for missing objections, compare candidate wording with cited evidence, detect contradictory records or flag low-confidence fields. Reviewers can receive a concise diff and risk-based queue rather than hundreds of undifferentiated suggestions.
Those automated checks reduce the work of verification; they do not grant an agent authority it lacks. The accountable person or authorized organizational process still decides what becomes shared policy.
Where AuzzurA DM fits
DM is designed around this candidate-to-approved transition. Evidence remains traceable, candidate interpretation is kept separate from trusted memory, and approved decisions, rules and skills can be resolved for later human or agent tasks. When a connected agent learns something during work, it can propose a new candidate that returns through review.
DM does not claim that every proposed extraction is correct or that its own approval gate replaces runtime permissions. It gives the team a controlled place to decide which knowledge should influence future work.
The follow-up challenge: making review proportional
Treat a minor wording correction differently from a new security rule. Define who may approve each class, what evidence is required, and when prior records must be revisited. Track false positives, review time and downstream corrections. Trust comes from an inspectable process, not from calling the model confident.
Further reading
The scenarios above are illustrative, not customer case studies. Forum posts reflect individual experiences, not representative statistics. DM product capabilities are described as design intent and should be checked against the current release before publication.
Put shared context to work.
DM is AuzzurA’s Beta product for human + AI teams. Sign up or sign in through the DM portal.